The Honeymoon Problem
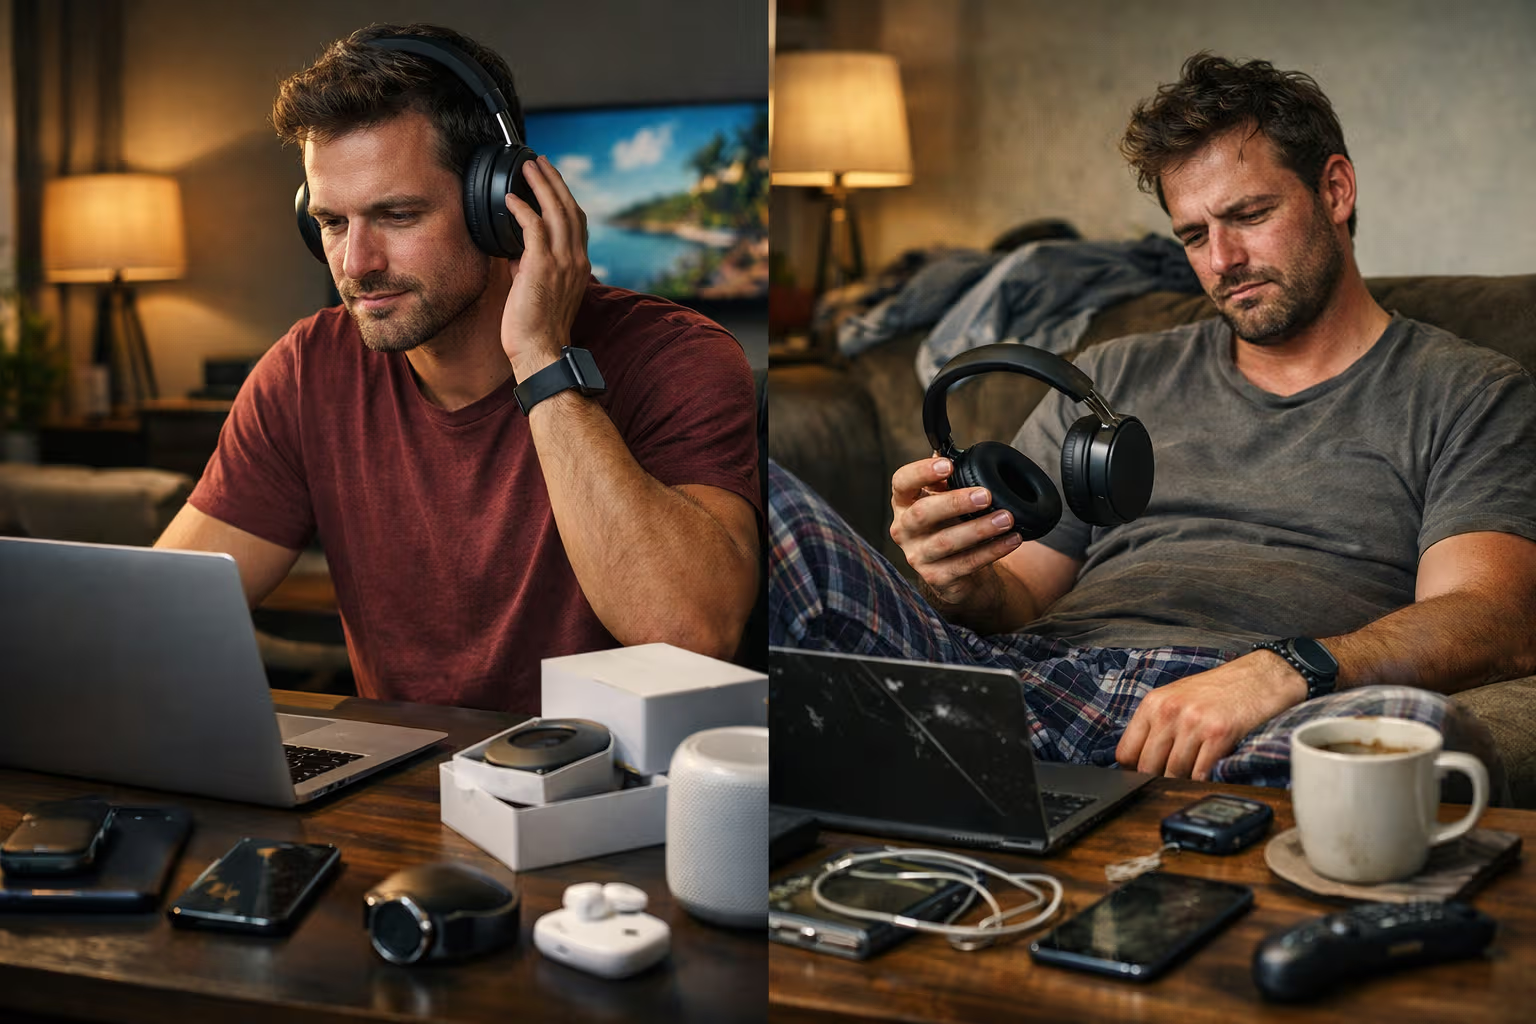
Every product has a honeymoon phase. The box opens. The setup completes. Everything feels fresh, fast, promising. You notice the features. You appreciate the design. You tell yourself this purchase was justified.
Three months later, reality intrudes. The features you noticed on day one aren’t the features you use daily. The design elements that impressed you initially now irritate through repetition. The product you tested isn’t quite the product you’re living with.
This gap between testing and living explains why so many highly-rated products disappoint in practice, and why some poorly-reviewed products earn fierce loyalty from long-term users. The review captured a moment. Life happens over months and years.
My British lilac cat, Muffin, demonstrates this principle with every new cat bed I purchase. Day one: curious sniffing, tentative sitting, apparent approval. Day thirty: complete abandonment in favor of the cardboard box the bed arrived in. Her initial assessment, while genuine, predicted nothing about long-term adoption.
Product reviews—including professional ones—suffer from the same temporal blindness. Reviewers typically spend days or weeks with products before publishing. That’s enough time to discover features but not enough time to discover friction. The review reflects testing conditions, not living conditions.
What Testing Captures
Testing reveals certain product qualities reliably. First impressions, setup experience, feature presence, basic functionality, obvious design flaws—all emerge within hours or days of use.
A competent tester can evaluate:
Performance Benchmarks: Does the laptop render video at advertised speeds? Does the phone achieve claimed battery life under controlled conditions? Does the software complete operations within reasonable timeframes? These metrics remain relatively stable.
Feature Completeness: Does the product do what the marketing materials claim? Are advertised capabilities actually present and functional? Testing catches missing or broken features.
Build Quality Indicators: Materials feel cheap or premium. Buttons click satisfyingly or mushily. Screens display accurately or with noticeable flaws. Physical quality reveals itself quickly.
Competitive Positioning: How does this product compare to alternatives on measurable dimensions? Price-to-feature ratios emerge from straightforward comparison.
Initial Learning Curve: How difficult is the product to understand? How long until basic competence? Early usability problems surface rapidly.
These testing-accessible qualities matter. They’re not nothing. But they represent perhaps 30% of what determines whether a product serves you well over years of ownership.
What Only Living Reveals
The remaining 70% emerges slowly, through accumulated daily interactions that no testing period adequately simulates.
Workflow Integration: How does this product fit into your actual routines? Testing involves deliberately using the product. Living involves the product existing within a context of other tools, habits, and constraints. Integration problems surface when the product must coexist with everything else you do.
Edge Case Accumulation: Products encounter unusual situations infrequently. Over weeks, you might hit one edge case. Over months, you’ll hit dozens. How the product handles these accumulated anomalies determines reliability perception far more than smooth operation under normal conditions.
Update Trajectory: Software products evolve continuously. The product you bought transforms through updates—sometimes improving, sometimes degrading. Living with a product means living with its update philosophy, not just its launch-day capabilities.
Support Quality: Eventually something breaks or confuses. Testing rarely triggers support interactions. Living inevitably does. The support experience—responsive or frustrating, competent or useless—dramatically affects product satisfaction.
Degradation Patterns: Batteries lose capacity. Moving parts wear. Software accumulates cruft. Performance degrades. These trajectories only reveal themselves over extended periods, often after warranties expire and reviews are long forgotten.
Habit Friction: Small inconveniences compound. A two-second delay barely registers in testing. That same delay, encountered fifty times daily for three years, represents hours of accumulated frustration. Living calculates these compound costs; testing cannot.
How We Evaluated
To understand the testing-versus-living gap, we conducted longitudinal analysis across multiple product categories:
Step 1: Initial Assessment Collection We gathered first-week impressions from 200 participants across five product categories: smartphones, laptops, wireless earbuds, smart home devices, and productivity software. Participants rated satisfaction and predicted long-term happiness.
Related reading
Step 2: Extended Usage Tracking Participants continued using products for twelve months minimum, completing monthly check-ins documenting satisfaction changes, discovered issues, and revised opinions.
Step 3: Prediction Accuracy Analysis We compared initial predictions against twelve-month assessments, identifying which product qualities participants accurately predicted and which surprised them.
Step 4: Professional Review Comparison We matched participant products against professional reviews published near purchase dates, measuring correlation between professional assessments and participant long-term experience.
Step 5: Pattern Identification We analyzed which product characteristics showed greatest divergence between testing-period assessment and living-period assessment, identifying systematic blind spots.
The findings confirmed intuitions but quantified them usefully. First-week satisfaction predicted twelve-month satisfaction with only 0.41 correlation—barely better than random. Certain product categories showed worse prediction accuracy than others, with software products proving particularly difficult to assess early.
The Software Paradox
Software products exhibit the testing-living gap most severely. Physical products at least have fixed properties—the chair’s comfort on day one resembles its comfort on day three hundred. Software shifts beneath you.
Consider a note-taking application. Testing reveals the interface, features, sync capabilities, and basic performance. You might genuinely prefer it to alternatives during testing. You adopt it.
Months later, the reality diverges from the test:
Feature Churn: The interface reorganizes in ways you didn’t request. Features you relied upon disappear. New features you don’t need clutter familiar workflows. The product you tested no longer exists.
Ecosystem Dependencies: The app integrated smoothly with your other tools during testing. Then one of those tools updates, breaking integration. The vendor blames the other vendor. You suffer the consequences.
Scaling Behavior: With fifty notes, everything performed acceptably. With five thousand notes, search slows, sync strains, and the application creaks under accumulated data weight.
Business Model Evolution: The free tier that attracted you during testing transforms into paid-only. The reasonable subscription doubles. The company gets acquired and pivots priorities. Your commitment to their product counts for nothing in their calculations.
Software testing evaluates a snapshot. Software living involves a trajectory you cannot observe during testing and cannot control afterward.
The Ritual Revealer
Daily rituals expose product qualities invisible to testing. Consider the morning coffee routine with a new espresso machine.
Testing Observation: The machine produces excellent espresso. Temperature is accurate. Crema is appropriate. The learning curve is manageable. Reviews would rate it highly.
Living Reality: The water reservoir requires refilling every three days and sits in an awkward position requiring machine movement. The drip tray overflows precisely when ignored. The cleaning cycle demands attention at inconvenient moments. The grinder sounds acceptable during deliberate testing but grating at 6 AM before caffeine takes effect.
None of these frictions appear in specifications or reviews. They emerge only through repeated daily encounters with the product in its actual context of use.
Muffin’s breakfast routine similarly exposes product qualities I’d never notice through deliberate testing. The automatic feeder that seemed quietly elegant in store demonstrations produces a servo whir triggering her “food imminent” excitement at 5:47 AM, thirteen minutes before I wanted consciousness. Living revealed what testing concealed.
The Diminishing Returns of Features
Feature lists dominate product marketing and heavily influence purchasing decisions. Testing naturally emphasizes features—reviewers document what products can do, providing concrete evidence of capability.
Living reveals that most features don’t matter.
Research consistently shows that users regularly employ a small fraction of available features. A word processor with two hundred features serves users who engage with perhaps twenty. The remaining hundred-eighty features create complexity without utility—menu clutter, documentation burden, and cognitive overhead without corresponding benefit.
But testing doesn’t reveal this pattern. During testing, you might explore features deliberately. “Can it do X? Yes. Can it do Y? Yes.” The feature presence registers as positive. Only through living do you discover that X and Y never enter your actual workflows.
The products that test best often feature-bloat their way to impressive specification sheets. The products that live best often embrace restraint, doing fewer things more gracefully. These qualities diverge systematically.
The Weight of Minor Irritations
Human psychology handles one major problem better than ten minor problems. A product with one significant flaw but otherwise excellent experience often lives better than a product with no major flaws but constant small irritations.
Testing tends to catch major flaws and miss minor irritations. The major flaws appear quickly and demand attention. The minor irritations seem negligible individually—surely you can tolerate a slightly awkward button placement, a marginally slow response, a mildly confusing menu structure.
Compound those minor irritations across thousands of interactions, and the calculation changes entirely.
I call this the papercut principle. A single papercut barely registers. Ten papercuts across a day becomes a persistent low-grade suffering. Products accumulate papercuts that testing cannot detect but living cannot ignore.
Consider wireless earbuds. Testing evaluates sound quality, connection stability, comfort during extended wear, and battery life. These matter. But living reveals different dimensions:
- How many steps to check remaining battery?
- How reliably do they pause when removed?
- How often does automatic ear detection misfire?
- How annoying is the charging case’s opening mechanism?
- How visible are fingerprints on the surface?
- How frequently do firmware updates reset preferences?
Each individual item seems trivial. Collectively, they determine whether earbuds become daily companions or drawer residents.
The Commitment Asymmetry
Testing involves low commitment. If the product disappoints, you return it, switch to alternatives, or simply stop using it. This freedom subtly affects assessment—problems feel solvable because escape remains easy.
Living involves high commitment. Data migrates into the product. Workflows adapt around it. Muscle memory develops. Switching costs accumulate. The product you can easily abandon during testing becomes the product you’re stuck with during living.
This commitment asymmetry means testing systematically underweights switching costs and overweights initial impressions. The product that’s 10% better on day one but 20% harder to leave becomes problematic only after the exit becomes costly.
Ecosystems exploit this asymmetry deliberately. Apple, Google, and Microsoft all design products that test competitively but lock users in progressively. The testing experience feels comparable across ecosystems. The living experience involves accumulated lock-in that makes switching increasingly painful.
Smart consumers consider switching costs during testing. But accurately predicting future switching costs requires imagination that testing doesn’t naturally encourage.
The Social Dimension
Products exist within social contexts that testing cannot replicate. Your phone doesn’t just serve you—it mediates communication with others whose device choices affect your experience.
Messaging Compatibility: iMessage works beautifully among iPhone users and terribly with Android users. Testing with your existing device mix shows current compatibility. Living involves changing device mixes as friends, family, and colleagues switch platforms.
Feature Dependence: You adopt a product feature. Others come to expect it. “Share your location” seemed optional during testing. Now your family expects real-time location sharing, and disabling it creates social friction.
Network Effects: Some products improve as more people adopt them. Others degrade. Video calling quality depends on both endpoints. Collaboration tools require collaborators. Social products need society. Testing evaluates individual experience; living involves collective dynamics.
Status Signaling: Whether we admit it or not, products signal identity. The laptop you open in meetings, the earbuds visible during commutes, the smartwatch on your wrist—all communicate something to observers. Testing might ignore this dimension. Living cannot.
The Professional Review Problem
Professional reviewers face structural constraints that systematically bias their assessments toward testing over living.
Time Pressure: Publications compete on speed. Getting reviews live at product launch drives traffic. Extended testing periods mean delayed publication means reduced relevance.
Sample Access: Review units arrive near launch and often must be returned. Reviewers cannot keep products for months of living-style evaluation.
Incentive Structures: Publications need manufacturer relationships for ongoing review access. Consistently negative assessments—even accurate ones—risk future access. This creates subtle pressure toward favorable coverage.
Related reading
Expertise Paradox: Professional reviewers develop deep product category knowledge enabling sophisticated testing but creating distance from typical user experience. The reviewer’s fiftieth phone evaluation differs fundamentally from your first phone purchase in years.
Audience Expectations: Readers expect reviews to provide definitive guidance. Acknowledging that definitive assessment is impossible undermines the review’s perceived value. Reviews project certainty that honest assessment wouldn’t support.
None of this makes professional reviews worthless. But consumers should understand reviews as testing reports with inherent living-phase limitations—valuable inputs but insufficient for confident decision-making.
The User Review Compensation
User reviews theoretically provide the living-phase perspective professional reviews lack. People who’ve owned products for months or years share experiences reflecting accumulated use.
But user reviews carry their own systematic distortions:
Selection Bias: Users motivated to write reviews skew toward extreme experiences. Those with unremarkable experiences rarely bother. The distribution of reviews doesn’t match the distribution of experiences.
Timing Bias: Reviews cluster near purchase dates, when honeymoon effects still apply. Long-term owners rarely return to update initial assessments.
Technical Variance: User problems often reflect individual circumstances—specific usage patterns, environmental factors, or configuration choices—rather than product qualities. Distinguishing product issues from user issues requires technical sophistication readers may lack.
Manipulation: Fake reviews, incentivized reviews, and competitor sabotage pollute user review ecosystems. Platforms attempt moderation but achieve only partial success.
The optimal approach combines professional and user reviews while discounting both appropriately—recognizing professional reviews’ testing bias and user reviews’ selection bias, extracting signal from both while trusting neither completely.
The Try Before You Buy Illusion
Stores offer product trials. Software provides free tiers. Electronics retailers stock demo units. These opportunities theoretically allow testing before commitment.
But store testing conditions differ fundamentally from living conditions:
Environmental Mismatch: Testing a laptop in a store’s fluorescent lighting reveals nothing about screen performance in your home office. Testing speakers against store ambient noise tells you nothing about apartment living. The environment dramatically affects product experience.
Duration Mismatch: Thirty minutes with a product cannot reveal what three months reveals. Comfort that seems adequate during brief testing becomes inadequate during extended use.
Context Mismatch: Store testing lacks your files, your preferences, your workflows, your other devices. The product exists in isolation from the ecosystem it must eventually join.
Pressure Mismatch: Sales presence, other customers, and time constraints create artificial testing conditions. Deliberate assessment differs from natural use.
Free software trials face similar problems. Thirty days is enough to test features but not enough to discover living-phase issues. The trial optimizes for conversion, not for accurate assessment of fit.
Building Your Own Testing Framework
Given the limitations of external reviews and store trials, what can individual consumers do to bridge the testing-living gap?
Several strategies improve assessment accuracy:
Extend Timelines: If return windows allow, don’t form final opinions until those windows nearly close. Use the full thirty days before deciding. Time reveals what snap judgments miss.
Simulate Living Conditions: Don’t deliberately test—just use the product normally within your actual routines. Let it encounter your real constraints rather than artificial evaluation scenarios.
Document Friction: Keep notes when products frustrate you, even mildly. After a week, review those notes. Patterns emerge that moment-to-moment experience obscures.
Seek Long-Term Users: Find forums, communities, or individuals who’ve used products for extended periods. Their experience provides living-phase data testing cannot.
Weight Switching Costs: Before purchasing, honestly assess what abandonment would require. Products with high switching costs deserve more rigorous testing than easily-replaceable products.
Trust Reluctant Recommendations: Enthusiastic early reviews reflect honeymoon effects. Recommendations from long-term users who acknowledge flaws but continue using products suggest genuine living-phase satisfaction.
The Muffin Methodology
Muffin’s approach to product evaluation, while feline-specific, offers principles applicable to human product assessment.
Ignore Initial Impressions: She shows polite interest in new items regardless of eventual adoption. First encounters provide insufficient information.
Test Under Real Conditions: She doesn’t perform deliberate product testing. She simply lives her life and lets products prove their worth within actual routines.
Abandon Without Guilt: If something doesn’t serve her needs, she stops using it immediately regardless of how much I spent. Sunk cost fallacy doesn’t trouble cats.
Prioritize Comfort Over Features: The fancy heated cat bed with multiple temperature settings loses to the plain cardboard box. Features matter less than fundamental fit with actual needs.
Revisit Occasionally: Products abandoned might get second chances. Circumstances change. What didn’t work before might work now. Assessment is ongoing, not final.
I’m not suggesting you knock products off tables to test their durability or sleep on every surface in your home. But the underlying principles—extended evaluation, authentic conditions, willingness to abandon, prioritizing core needs, remaining open to reassessment—serve human consumers as well as they serve cats.
Category-Specific Considerations
The testing-living gap varies by product category. Some categories allow relatively accurate early assessment; others diverge dramatically.
Relatively Predictable (Testing ≈ Living):
- Simple tools without software components
- Products with minimal learning curves
- Items used occasionally rather than daily
- Products with short expected lifespans
Moderately Unpredictable:
- Consumer electronics with firmware updates
- Subscription services with evolving feature sets
- Products requiring ecosystem integration
- Items used daily but with consistent use patterns
Highly Unpredictable (Testing ≠ Living):
- Complex software with frequent updates
- Products dependent on external services
- Items requiring significant workflow adaptation
- Products with heavy network effects
Adjust your testing rigor accordingly. A kitchen knife requires less extensive evaluation than productivity software. The knife’s qualities remain relatively stable; the software’s qualities shift continuously.
The Paradox of Research
More product research doesn’t necessarily improve decisions. At some point, additional information provides diminishing returns while consuming time and attention that has value.
The optimal research investment depends on:
Product Cost: Higher-priced items justify more research time. A $2,000 laptop merits more investigation than a $20 cable.
Switching Difficulty: Products that are hard to abandon warrant more upfront diligence than easily-replaced items.
Usage Frequency: Daily-use products affect experience more than occasional-use products, justifying greater research investment.
Category Familiarity: If you understand a product category well, marginal research provides less value. If the category is new to you, research yields more insight.
Risk Tolerance: If product disappointment would be very costly (financially, professionally, emotionally), invest more in assessment. If disappointment is easily absorbed, research less.
Related reading
The goal isn’t maximum information—it’s optimal information given your constraints and the stakes involved.
Manufacturers Know This
Product manufacturers understand the testing-living gap better than consumers do. Their design decisions often optimize for testing-phase impression over living-phase satisfaction.
Launch-Day Performance: Products are tuned to benchmark well at launch, when reviews happen. Performance may degrade through updates once reviews are published and purchases committed.
Demo Mode Polish: Features encountered during typical testing receive disproportionate design attention. Features encountered only through extended use receive less.
Review Unit Selection: Review samples sometimes receive extra quality control attention that production units don’t. The product reviewers test may literally differ from the product consumers buy.
Planned Obsolescence Timing: Products may be designed to degrade after typical testing windows close. Batteries, moving parts, and software support all follow predictable degradation curves.
Marketing Emphasis: Specifications emphasized in marketing are often testing-phase metrics (benchmark scores, feature counts, measurable specifications) rather than living-phase qualities (reliability, support quality, update trajectory).
This isn’t universal conspiracy—many manufacturers genuinely prioritize long-term satisfaction. But the incentive structures reward testing-phase optimization, and consumers should adjust expectations accordingly.
The Living-First Mindset
Adopting a living-first mindset means prioritizing long-term ownership experience over initial impressions when making product decisions.
Practically, this involves:
Asking Different Questions: Instead of “what features does this have?” ask “what will using this daily for two years feel like?” Instead of “how does this compare in benchmarks?” ask “how does this compare in reliability and support?”
Valuing Different Sources: Weight long-term user reports over launch-day reviews. Prioritize information sources covering living-phase experience.
Accepting Different Tradeoffs: Sometimes the product with fewer features or lower benchmarks provides better living experience through superior reliability, simpler operation, or better support.
Maintaining Appropriate Skepticism: First impressions lie. Honeymoon phases end. The product you think you’re getting is not entirely the product you’ll be living with.
Building Escape Routes: When possible, choose products that allow easier exit if living experience disappoints. Avoid ecosystem lock-in that makes abandonment costly.
The Uncomfortable Truth
Here’s what product manufacturers, reviewers, and often consumers themselves prefer not to acknowledge: predicting living-phase experience from testing-phase assessment is genuinely difficult. Uncertainty is irreducible.
You can minimize bad decisions through careful research and extended evaluation. You cannot eliminate them. Products that seem perfect during testing sometimes disappoint during living. Products approached skeptically sometimes exceed expectations. The gap between testing and living ensures some decisions will prove wrong regardless of diligence.
Accepting this uncertainty paradoxically improves decision-making. You stop seeking impossible certainty. You invest appropriate rather than excessive research effort. You choose products that allow course correction rather than demanding permanence.
Muffin has just walked across my keyboard, expressing indifference to this entire analysis. She doesn’t need frameworks for product evaluation. She simply uses things that work and abandons things that don’t, without agonizing over the decision.
Perhaps that’s the ultimate lesson. Test what you can. Live with what you must. Stay willing to change course when living reveals what testing couldn’t. The difference between testing a product and living with it is the difference between visiting a place and making it home—and both experiences have value, but only one reveals the truth.
The product you test is an introduction. The product you live with is a relationship. Evaluate accordingly.
One email a month: new articles, reviews and the upcoming live webinar + free recording. No spam, unsubscribe anytime.